

Best Paper Award at the Korea Computer Congress 2026 (KCC2026)
Files

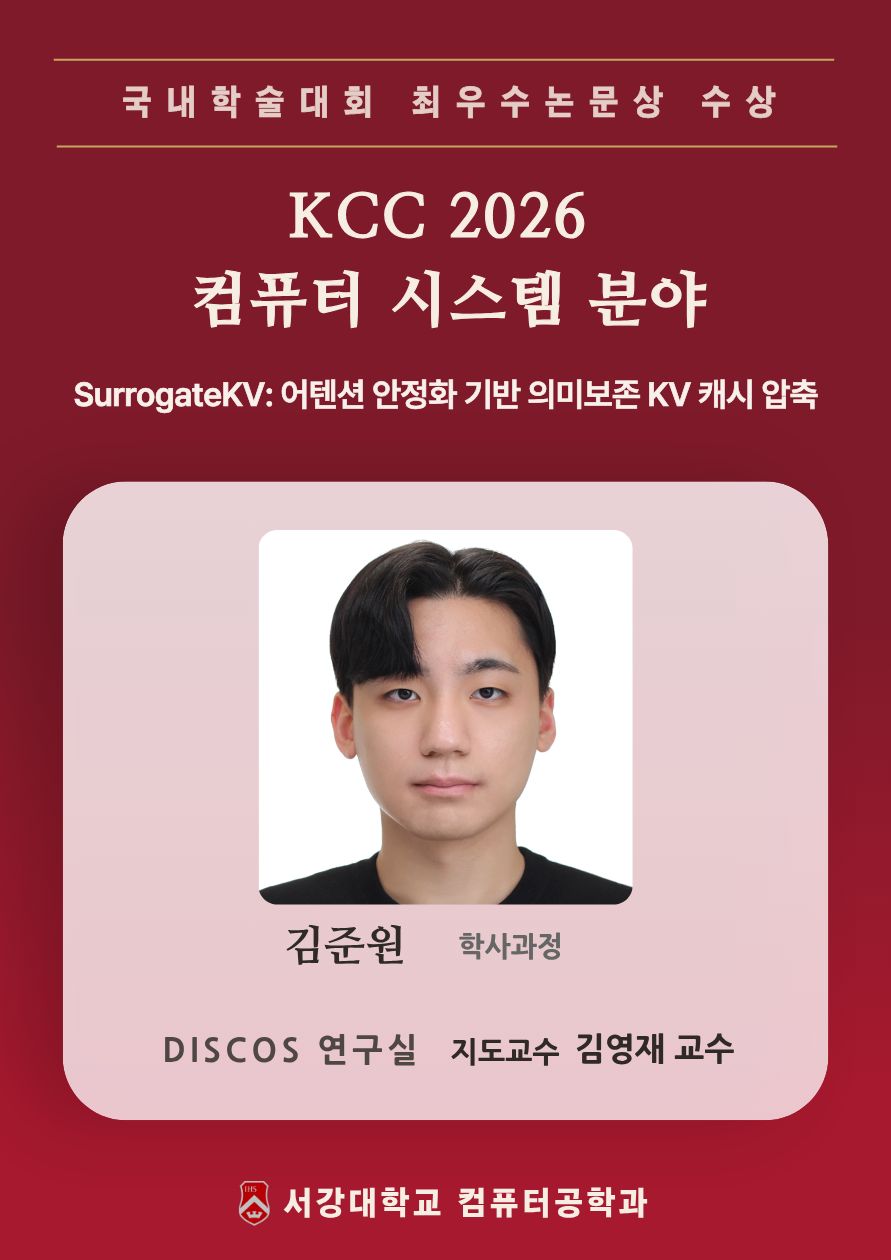
At the Korea Computer Congress 2026 (KCC2026), held over three days from 24 June 2026, the paper 'SurrogateKV: Semantics-Preserving KV Cache Compression Based on Attention Stabilization' by Kim Jun-won of the Department of Computer Science & Engineering (Computer Science & Engineering '21; supervisor: Professor Kim Young-jae) received the Best Paper Award in the computer systems division.
In long-context inference with large language models (LLMs), the KV cache that stores the key and value tensors of previous tokens is the main bottleneck determining GPU memory usage, inter-worker transfer volume and time to first token (TTFT). Existing research on KV cache compression has chiefly reduced cache size by removing chunks of low importance, but this has the limitation that the removed spans are excluded entirely from attention in subsequent decoding steps, distorting the attention distribution and causing loss of context.
To alleviate this limitation, the research proposes SurrogateKV, a new KV cache compression technique that does not delete low-importance KV chunks outright but replaces them with a single surrogate KV token that attention can still refer to. This retains the information needed in long contexts while reducing cache size and transfer cost, and mitigates the loss of context that can occur with existing removal-based approaches. In long-context question answering, long-document summarization and retrieval-based benchmarks, the proposed technique performed more stably than existing pruning methods, scoring 9.73 points higher than PyramidKV when only 25% of the KV cache is retained. It also limited the increase in TTFT to at most 22.9 ms compared with FullKV, which uses the entire original KV cache, demonstrating that both the efficiency and the stability of long-context LLM serving can be improved together.