

Paper Accepted at 'NAACL 2024', Listed at BK IF2 in Natural Language Processing
Files

The research team of Professor Koo Myoung-wan, Department of Computer Science & Engineering,
Paper Accepted at 'NAACL 2024', Listed at BK IF2 in Natural Language Processing
▲ (From left) Professor Koo Myoung-wan, Department of Computer Science & Engineering; Kim Min-ju and Jung Hae-in, master's students, Graduate Department of Artificial Intelligence
A paper by the Intelligent Spoken Dialogue Systems (ISDS) research team, supervised by Professor Koo Myoung-wan of the Department of Computer Science & Engineering, has been accepted as a NAACL Findings Paper at the 2024 Annual Conference of the North American Chapter of the Association for Computational Linguistics (NAACL 2024).
NAACL is the North American chapter, established in 1998, of ACL, the most prestigious conference in natural language processing, and together with ACL and EMNLP is regarded as one of the world's three leading natural language processing (NLP) conferences. NAACL 2024 will be held in Mexico City, the capital of Mexico, from 16 to 21 June.
The paper by master's students Kim Min-ju and Jung Hae-in of the Graduate Department of Artificial Intelligence (joint first authors) and Professor Koo Myoung-wan (corresponding author), titled 'SELF-EXPERTISE: Knowledge-based Instruction Dataset Augmentation for a Legal Expert Language Model', will appear in the proceedings of NAACL 2024.
The team pointed out that when instruction datasets are generated automatically using a large language model (LLM), relying only on the model's built-in knowledge can produce hallucination — inaccurate or plausible-sounding false information. They identified as a particular problem the greater difficulty LLMs have in producing accurate information in specialist domains where accuracy matters, such as law. The team therefore proposed SELF-EXPERTISE, a new augmentation pipeline that overcomes the limitations of existing LLMs and automatically generates instruction datasets reflecting expert-level knowledge in fields such as law where accuracy is critical. Just as a teacher setting an exam refers to the textbook material within the examination scope, the approach has the LLM refer to knowledge when producing instruction, input and output triples, reducing hallucination and improving accuracy.
▲ The specialist-domain instruction dataset augmentation pipeline proposed in the paper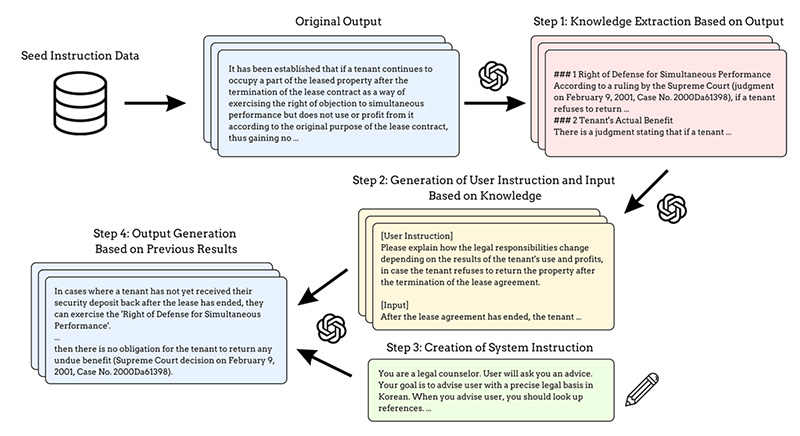
Using the legal-domain instruction dataset generated through SELF-EXPERTISE, the team trained a LLaMA-2 7B model to develop LxPERT, a legal specialist model, which achieved higher performance in the legal domain than other models including the existing GPT-3.5. The research shows that methods for generating instruction datasets grounded in accurate knowledge can play an important role in extending the range of LLM applications into specialist fields.
The master's students who took part in this research are respectively a DHE (Digital Human Entertainment) scholarship holder sponsored by Smilegate and a Smart AI scholarship holder sponsored by LG Electronics. They said: "We feel proud to have achieved a meaningful result in the field we have researched consistently throughout our master's studies," adding: "We want to contribute to society by researching technology that can help people's lives."
Professor Koo Myoung-wan said: "I will continue to take an interest and provide guidance so that more students can achieve good results."