

Regular Paper Accepted at the Outstanding International Conference IEEE International Conference on Cloud Computing (CLOUD) 2025
Files

Paper Accepted at the IEEE International Conference on Cloud Computing (CLOUD) 2025
Lee Hyung-woo, master's student (supervisor: Professor Kim Young-jae)
The paper 'Disk-Based Shared KV Cache Management for Fast Inference in Multi-Instance LLM RAG Systems', written by Lee Hyung-woo, master's student at the Data-Centric Computing and AI Systems Laboratory (DISCOS) (first author; supervisor Professor Kim Young-jae), Kim Ki-hyun (combined master's–doctoral), Kim Jin-woo (combined master's–doctoral), Professor So Jung-min and Professor Kim Young-jae (corresponding author), has been accepted for publication at The IEEE International Conference on Cloud Computing (CLOUD 2025).
Large language models (LLMs) such as GPT have recently entered deeply into our lives and are showing a wide range of possibilities. Retrieval-augmented generation (RAG), which helps LLMs draw on vast external knowledge to produce more accurate and richer answers, is growing ever more important. Using RAG, however, causes an explosive increase in the volume of data the LLM must process, so the time until the user receives a first answer grows longer and the overall throughput of the system falls. This is chiefly because the amount of computation surges in the 'prefill' stage, where the LLM first processes the input information.
AI technology today is expanding beyond simple information retrieval into solving complex problems and performing creative tasks. Supporting this progress requires research on system optimization so that core models such as LLMs can process vast amounts of data quickly and efficiently.
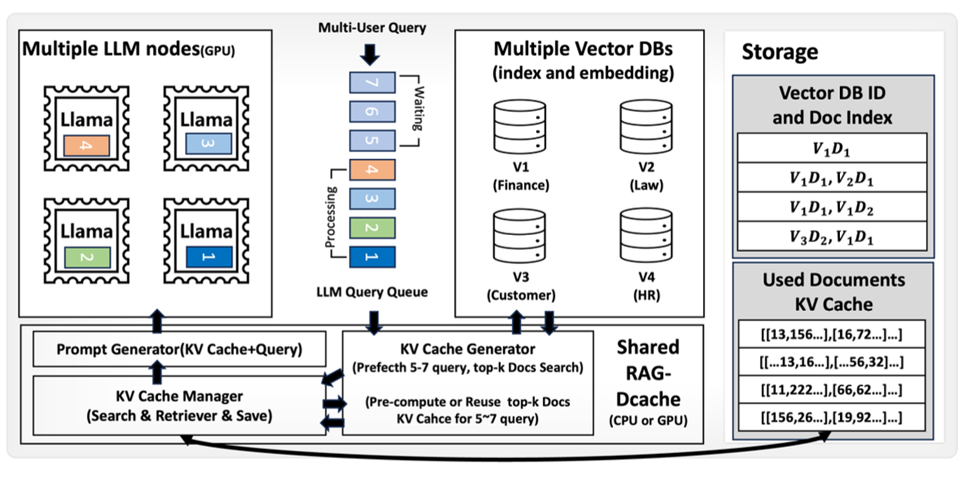
This research proposes Shared RAG-DCache, a disk-based shared key-value (KV) cache management system that aims to shorten LLM response times and increase throughput by improving the data processing pipeline so that AI systems achieve optimal performance. Shared RAG-DCache reduces the computation time of the prefill stage, the most time-consuming part of LLM inference.
The figure below shows the architecture of the Shared RAG-DCache system.
In a RAG-based multi-LLM service environment with two GPUs and one CPU, applying Shared RAG-DCache raised LLM throughput (requests processed per second) by up to 71% compared with not using the system, and reduced average response latency by up to 65%. This means that many users can use LLM services simultaneously with greater speed and comfort.
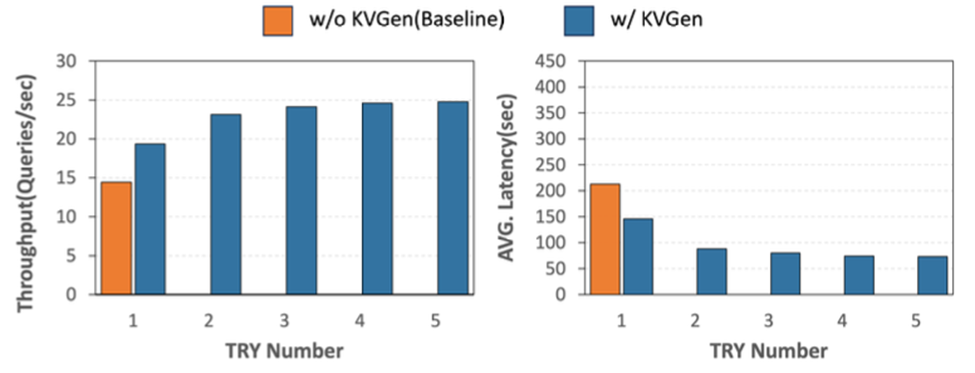
* w/ KVGen: shows the improved throughput and response speed when Shared RAG-DCache is used (blue).
Lee Hyung-woo, the paper's first author, said: "LLMs such as GPT are becoming ever smarter, but at the same time they face the technical challenge of processing more information quickly. To address this, our laboratory has formed an LLM systems research team under our supervisor and is working to optimize the performance of AI systems. I am very glad that this research allowed us to give concrete shape to an idea for improving the efficiency of handling user requests in RAG-based multi-LLM service environments and to obtain good results by demonstrating its effect. In an age when AI is changing the world, I believe research into the underlying system technology will become even more important, and I hope many undergraduates will take an interest in this fascinating field."
IEEE CLOUD is a conference that aims to exchange fundamental advances and real-world applications in cloud infrastructure, technology, applications and business, to identify new research topics and to define the future of cloud computing. This year's event will be held in Helsinki, Finland, from 7 to 12 July.
References:
● The IEEE International Conference on Cloud Computing CLOUD 2025
● Website : https://services.conferences.computer.org/2025/cloud/