

Regular Paper Accepted at the Outstanding International Conference IEEE International Conference on Cloud Computing (CLOUD) 2025
Files

Paper Accepted at the IEEE International Conference on Cloud Computing (CLOUD) 2025
Kim Ki-hyun, combined master's–doctoral student (supervisor: Professor Kim Young-jae)
The paper 'Cost-Efficient VM Selection for Cloud-Based LLM Inference with KV Cache Offloading', written by Kim Ki-hyun, combined master's–doctoral student at the Data-Centric Computing and AI Systems Laboratory (DISCOS) (first author; supervisor Professor Kim Young-jae), Kim Jin-woo (combined master's–doctoral), Jung Hyun-seon (master's) and Professor Kim Young-jae (corresponding author), has been accepted for publication at The IEEE International Conference on Cloud Computing (CLOUD 2025).
Large language models (LLMs) are rapidly establishing themselves as a core technology across many fields, but the high cost of the GPU virtual machines (VM) needed to run LLM inference services in the cloud has been noted as a major obstacle to commercialization. In particular, the KV cache data generated in large volumes during LLM inference frequently causes GPU memory shortages, and strategies for offloading the KV cache to CPU memory to manage this require a complex balancing act between system performance and cost.
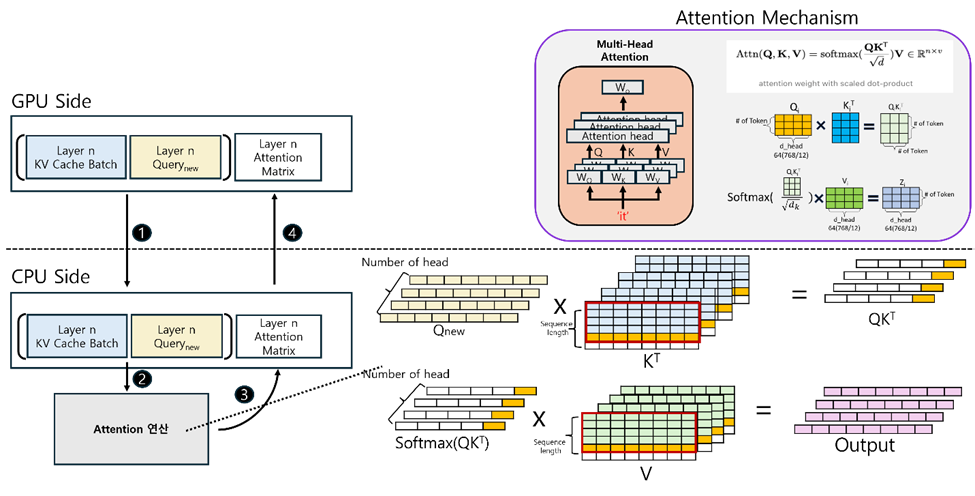
Figure 1. Concept of KV cache offloading: a core technique that reduces the burden on GPU memory by offloading part of the KV cache, which occupies a great deal of GPU memory during LLM inference, to CPU memory. This makes it possible to handle longer contexts or run larger batch sizes even with limited GPU memory.
The INFERSAVE framework proposed by the team was developed to resolve these practical problems of running LLMs in the cloud. INFERSAVE comprehensively analyses the user's service level objectives (SLO), the particular characteristics of the workload to be processed and budget constraints; on that basis it determines the optimal KV cache offloading strategy and automatically recommends the most cost-efficient cloud VM instance.
In experiments on AWS, applying INFERSAVE improved cost efficiency by up to 73.7% on online inference workloads by effectively selecting suitable low-cost VMs even without KV cache offloading, and delivered operating cost savings of up to 20.19% on offline inference workloads through KV cache offloading. These results clearly indicate that INFERSAVE is a practical solution that helps cloud users run LLM services more economically while reliably achieving the performance they want.
Kim Ki-hyun, the paper's first author, said: "The high cost of running LLMs in cloud environments is a major concern for many people. INFERSAVE, which we developed, precisely analyses each user's differing needs — their various service level objectives (SLO), budget and the characteristics of the workload to be processed — in order to solve exactly that problem. On that basis INFERSAVE recommends the optimal, tailored VM instance each user actually needs, helping them exploit the powerful performance of LLMs without unnecessary spending. Advances in AI models themselves are very important, but I am convinced that research into the system optimization that enables these models to be served efficiently and economically in real environments is one of the core technologies of the AI era. I look forward to seeing many undergraduates take an interest in and take on this important and fascinating field of systems research."
IEEE CLOUD is a conference that aims to exchange fundamental advances and real-world applications in cloud infrastructure, technology, applications and business, to identify new research topics and to define the future of cloud computing. This year's event will be held in Helsinki, Finland, from 7 to 12 July.
References:
● The IEEE International Conference on Cloud Computing CLOUD 2025
● Website : https://services.conferences.computer.org/2025/cloud/