

Regular Paper Accepted at the Outstanding International Conference Interspeech 2026
Files

The paper 'SAM: A Mamba-2 State-Space Audio-Language Model', written by doctoral student Lee Tae-han (first author), master's student Jung Jae-han and Professor Lee Hyuk-jun (corresponding author) of the Intelligent Computer Architecture and Embedded Computing Laboratory (ECL), has been accepted for publication as a regular paper at Interspeech 2026.
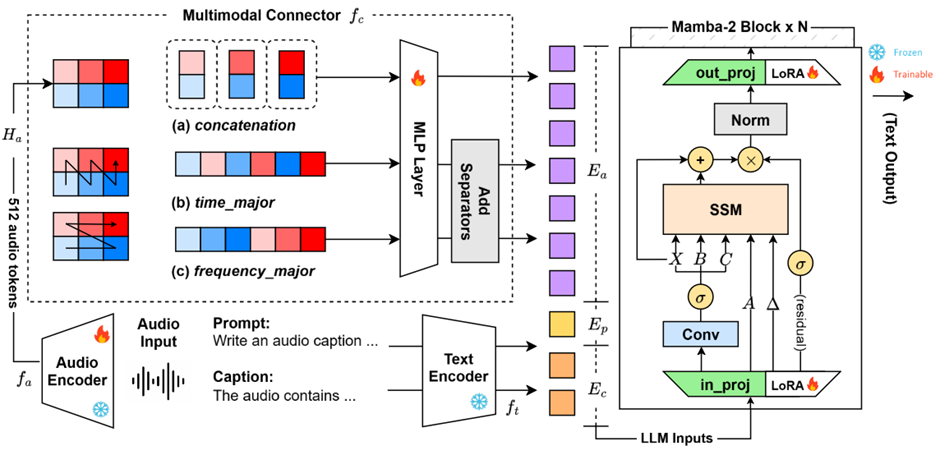
Figure 1. Architecture of the SSM-based audio-language model
The team proposes SAM (State-space Audio-language Model), a new audio-language model based on state-space models (SSM). SAM performs audio reasoning by combining an audio encoder with a Mamba-2 language model. The research shows that SAM-2.7B achieves strong performance on major benchmarks including AudioSet, AudioCaps and MMAU with fewer parameters than existing, larger 7B-class transformer-based audio-language models, demonstrating competitive performance. Going beyond a simple performance comparison, the research analyses how the SSM interacts with the output representation of the audio encoder. It finds that training the audio encoder jointly matters, and that giving the SSM a shorter token sequence compressed along the time axis is more effective than feeding it the long, uncompressed spectrogram token sequence. It also shows that adding true/false and multiple-choice training data greatly improves audio reasoning. The team plans to explore hybrid architectures combining the strengths of SSMs and transformers to further improve audio reasoning performance.
[References]
Paper link: https://arxiv.org/abs/2509.15680
Conference link: https://interspeech2026.org/en-AU