

Papers Accepted at INTERSPEECH, a World-Renowned Conference in Speech AI
Files

Two papers by master's students of the Intelligent Spoken Dialogue Systems Laboratory (ISDS) research team,
Accepted at INTERSPEECH, a World-Renowned Conference in Speech AI
▲ (Top row, from left) Professor Koo Myoung-wan, Department of Computer Science & Engineering; Choi Ye-rin, master's student, Department of Artificial Intelligence
(Bottom row, from left) Yeon Hee-yeon and Kim Min-ju, master's students, Department of Artificial Intelligence
Text-to-speech (TTS) synthesis and spoken language understanding (SLU) research by master's students of the University's Department of Artificial Intelligence will be presented at a world-renowned conference on spoken language processing.
Two papers submitted by master's students of the Intelligent Spoken Dialogue Systems Laboratory (ISDS), supervised by Professor Koo Myoung-wan of the Department of Computer Science & Engineering, have been accepted at INTERSPEECH 2023, to be held in Dublin, Ireland, from 20 to 24 August (local time).
The speech synthesis study 'DC CoMix TTS: An End-to-End Expressive TTS with Discrete Code Collaborated with Mixer', by master's student Choi Ye-rin of the Graduate Department of Artificial Intelligence (third semester) and Professor Koo Myoung-wan (corresponding author), presents a technique for enriching the emotional expression of synthesized speech. The team proposed using quantized vectors extracted from a neural audio codec model as model input so that acoustic information such as prosody can be richly captured during speech synthesis. With this method they demonstrated improved performance in speaker-independent prosody expression on both qualitative and quantitative evaluation.
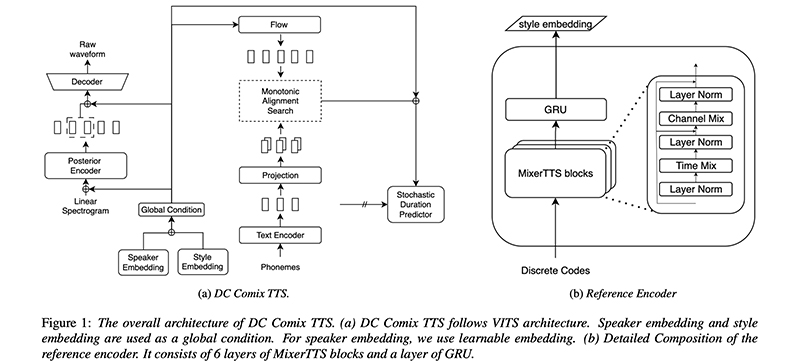
▲ Overview of the DcCoMix TTS architecture proposed by Choi Ye-rin, master's student in the Department of Artificial Intelligence
The paper 'I Learned Error, I Can Fix It!: A Detector-Corrector Structure for ASR Error Calibration', by master's students Yeon Hee-yeon (third semester) and Kim Min-ju (second semester) of the same department (joint first authors) and Professor Koo Myoung-wan (corresponding author), proposes a model that automatically corrects speech recognition errors in utterances. Speech recognition errors are regarded as a representative problem that degrades language understanding performance in the spoken dialogue pipeline. The proposed model consists of a detector trained by simulating a variety of speech recognition errors, and a corrector trained to predict the correct phrase for segments identified as errors. The team demonstrated experimentally that the proposed model improves performance on downstream spoken language understanding tasks.
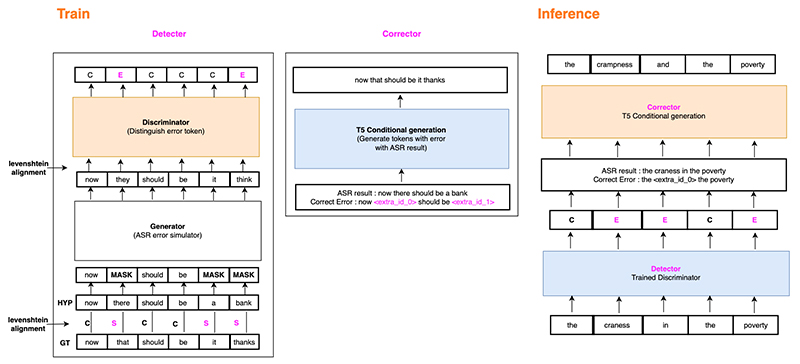
▲ Overview of the Detector-Corrector architecture proposed by Yeon Hee-yeon and Kim Min-ju, master's students in the Department of Artificial Intelligence
Both studies are achievements at an international conference by research teams composed entirely of master's students with relatively short track records in engineering research. The students who wrote these papers belong to the first and second cohorts of the Department of Artificial Intelligence, established last year. All majored as undergraduates in humanities, social science or convergence disciplines — economics (Choi Ye-rin), Korean literature (Kim Min-ju) and art & technology (Yeon Hee-yeon).
Professor Koo said: "INTERSPEECH is where the world's finest researchers in speech share their work, so this means our master's students are conducting research on a par with them," adding: "I will continue to guide my students so that they can find creative ways of solving problems in speech and language processing research."